
On 16 November 2026, LIBRA AI Technologies joined the 5th GenAI Summit as a Gold Sponsor. This year’s summit, themed “Agents at Work”, brought together nearly 2,500 professionals at the Stavros Niarchos Foundation Cultural Center in Athens.
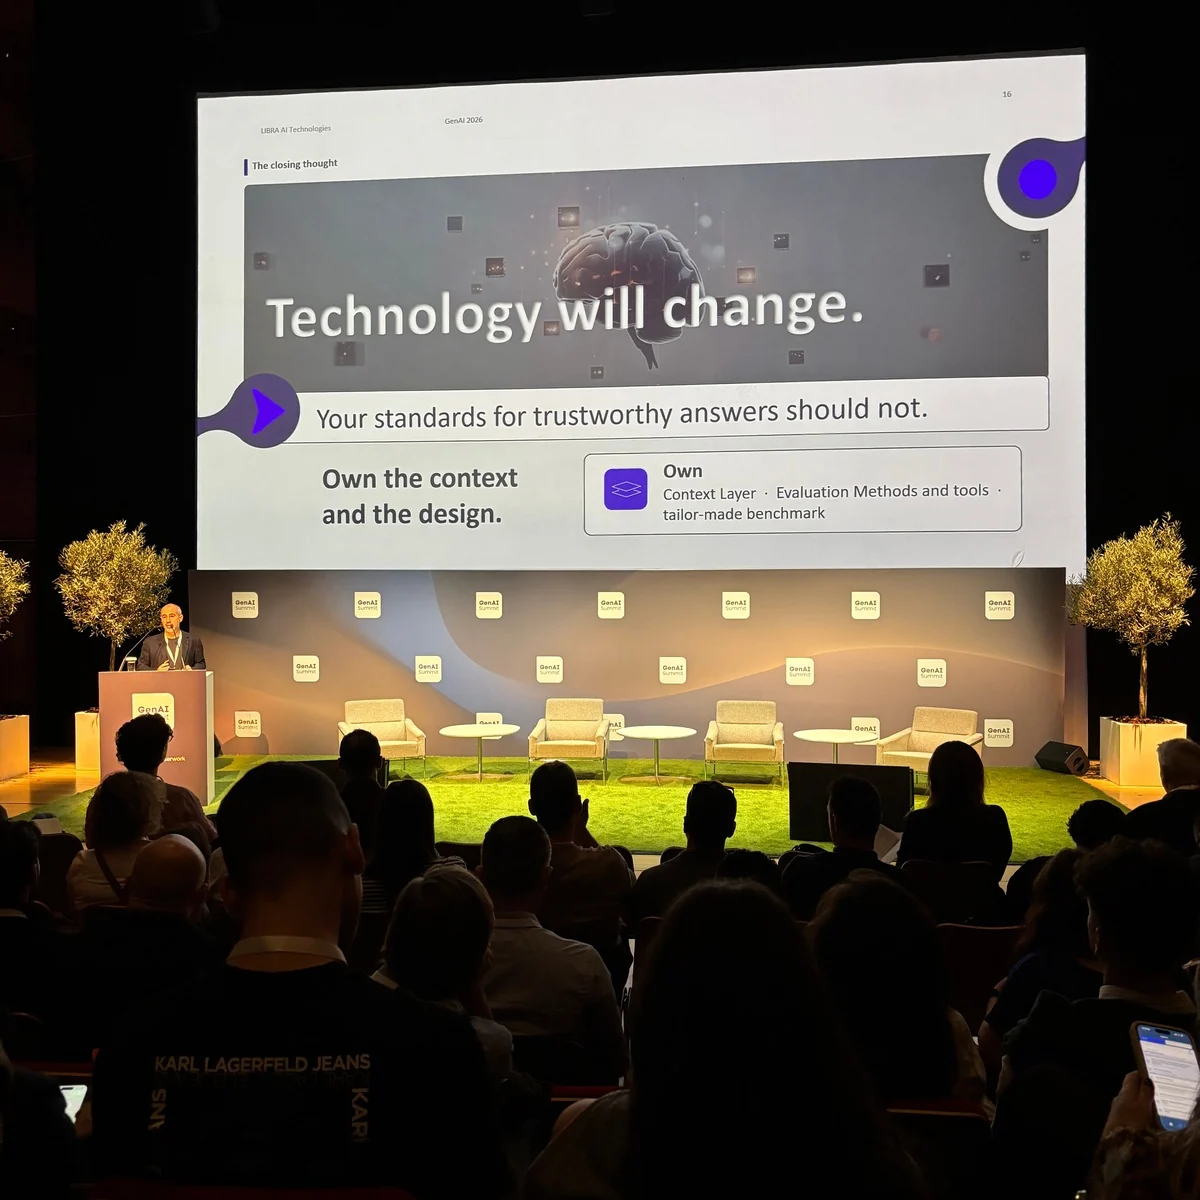
Our contribution to the programme focused on what it takes to put AI assistants into daily business use. Drawing on LIBRA’s work with legal documents, our CEO and Co-Founder, Yannis Kopsinis, shared how we build Agentic RAG systems that give professionals answers they can verify, and how we measure the cost of delivering those answers consistently.
The aim is to find the simplest system that can reliably answer the questions people need to ask. Getting there requires careful document preparation and a way to measure how each design choice affects answer quality, response time and running cost.
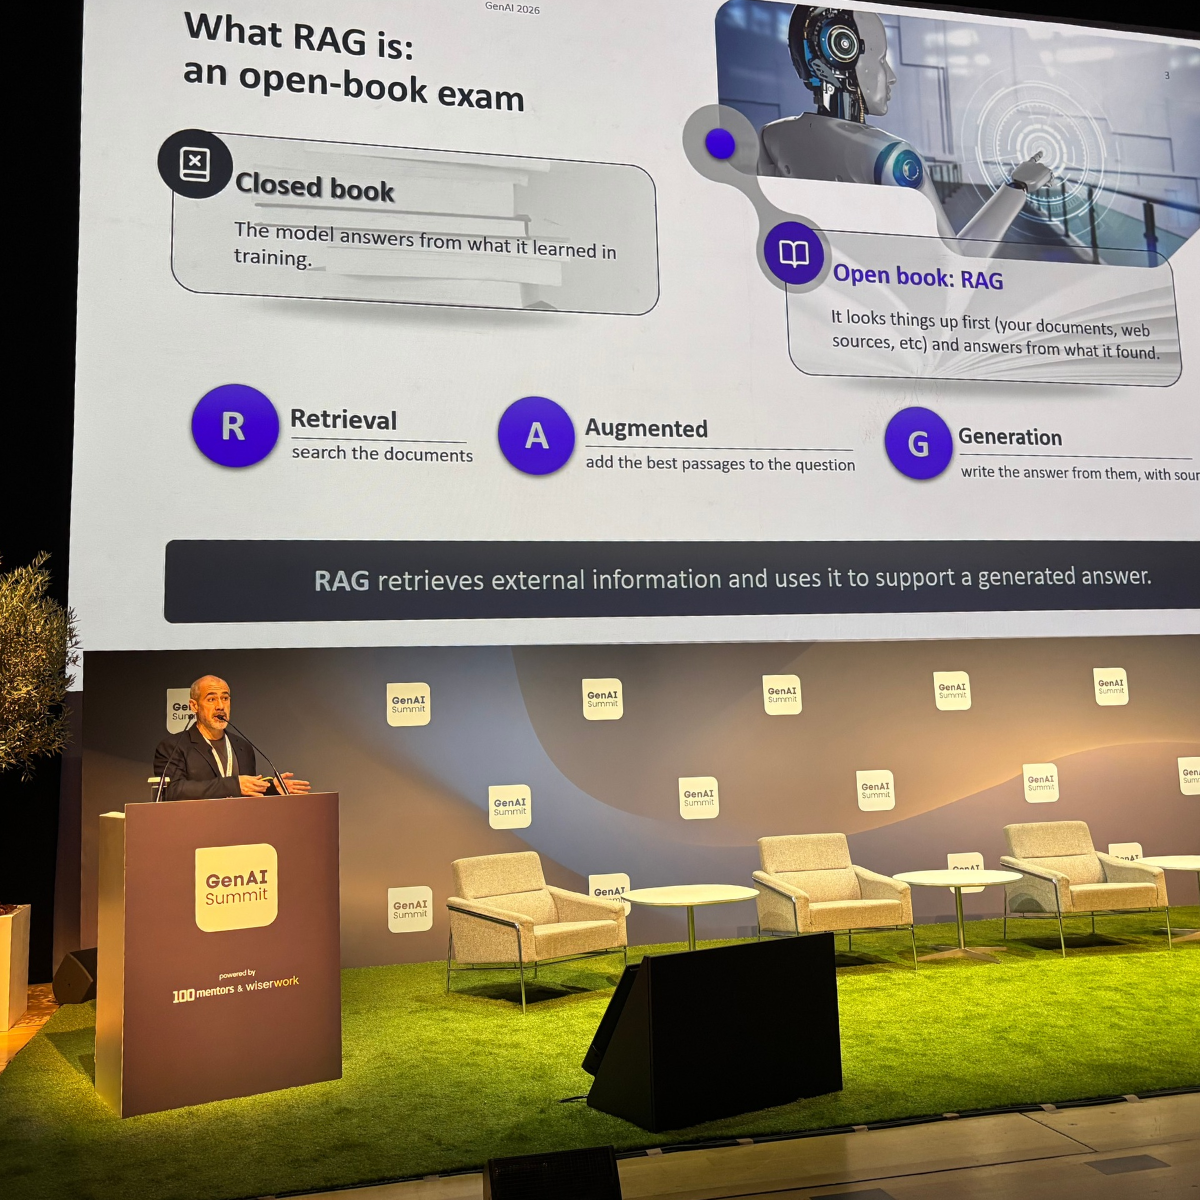
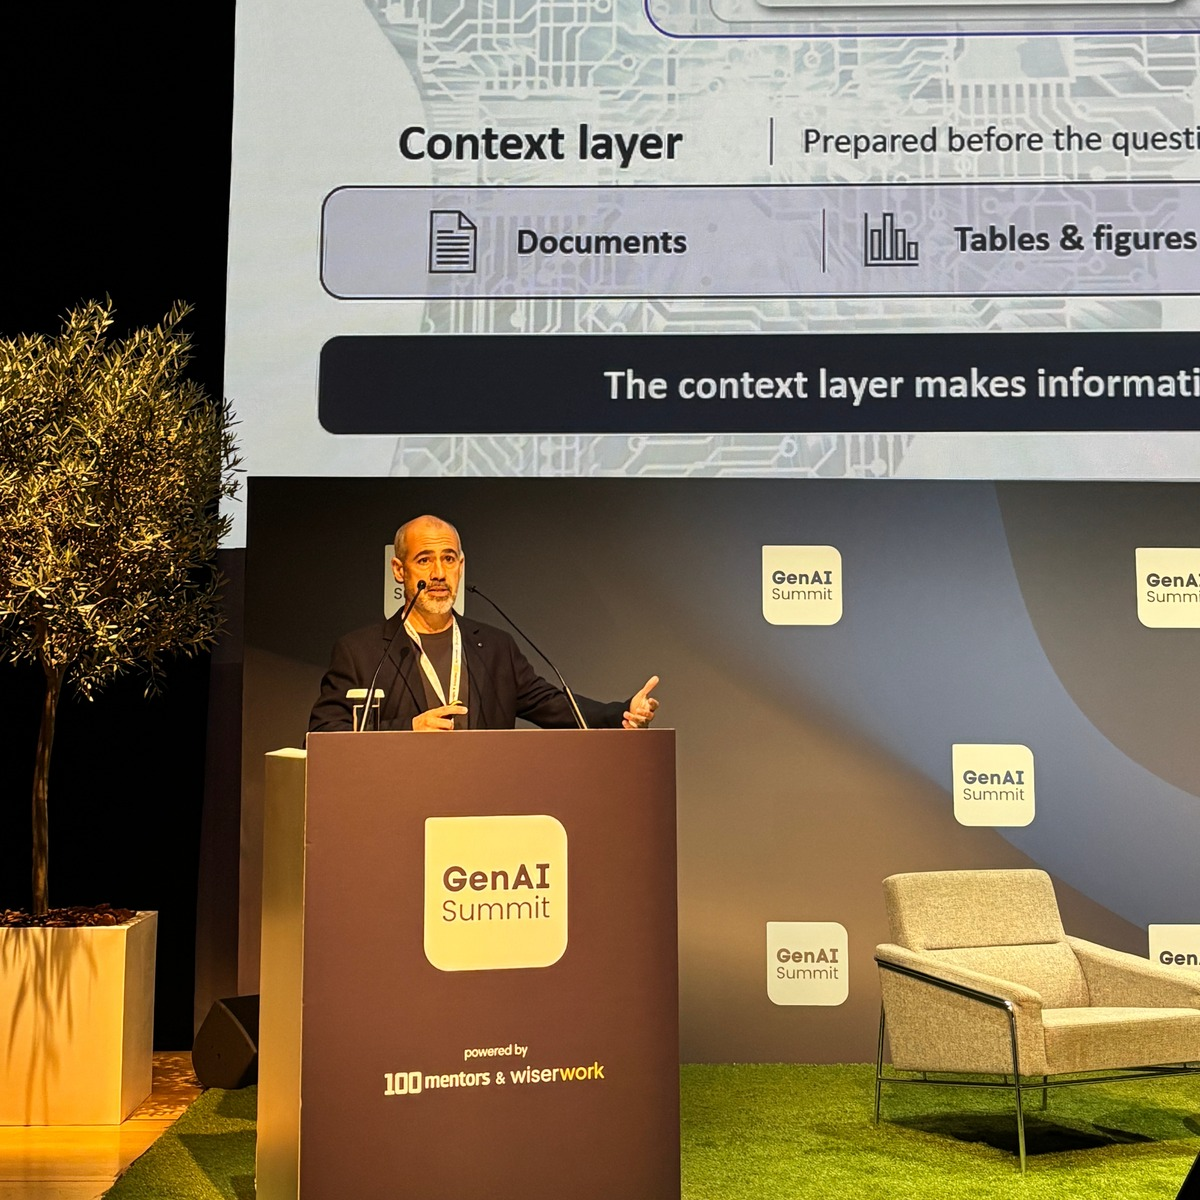
What makes an AI agent answer reliable?
Ιn legal documents, an exception or an effective date can change the answer. An assistant checking whether a customer was charged the correct fee needs to find the rule that applied at the time, check any relevant exceptions and show the passages that support its conclusion. That starts with how the documents are prepared. Dates, references and exceptions need to stay connected to the rules they qualify.
Agentic RAG gives the assistant flexibility in how it searches. It can answer a straightforward question after one search, follow a reference when the first result is incomplete or ask for a missing detail. When the available evidence falls short, it can explain what it still needs before reaching a conclusion.
When is a deeper search worth the cost?
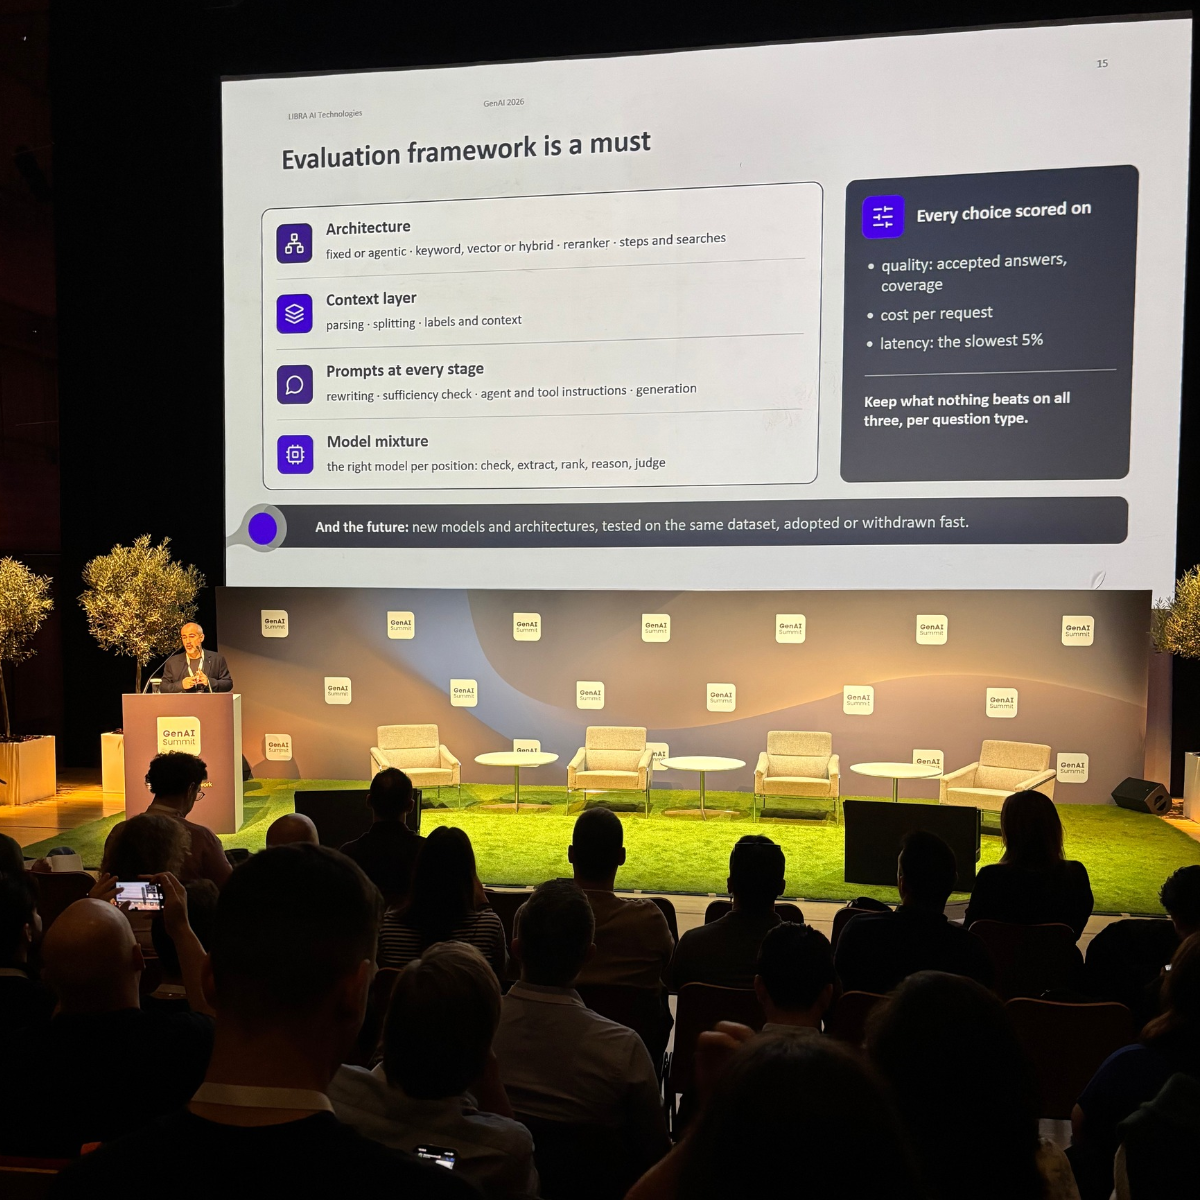
Each extra search or model call can add to the time and cost of an answer. A focused search may give users everything they need for a routine question. In a more complex case, checking one more source can change the conclusion.
We built the LIBRA AI RAG Evaluation Framework to measure that trade-off. Using real business questions and expected answers reviewed by domain experts, we compare different system designs on answer quality, response time and cost per question. After launch, the same tests help us decide whether a change is worth adopting, from a better way to read documents to a new search method or model.
Conversations beyond the stage
Throughout the summit, our team joined sessions and workshops on AI agents in business operations, security, governance and robotics. We also spoke with teams already deploying AI and organisations exploring where it could fit into their work. Those conversations gave us a chance to hear how others are tackling similar challenges and discuss where LIBRA’s work could be useful.
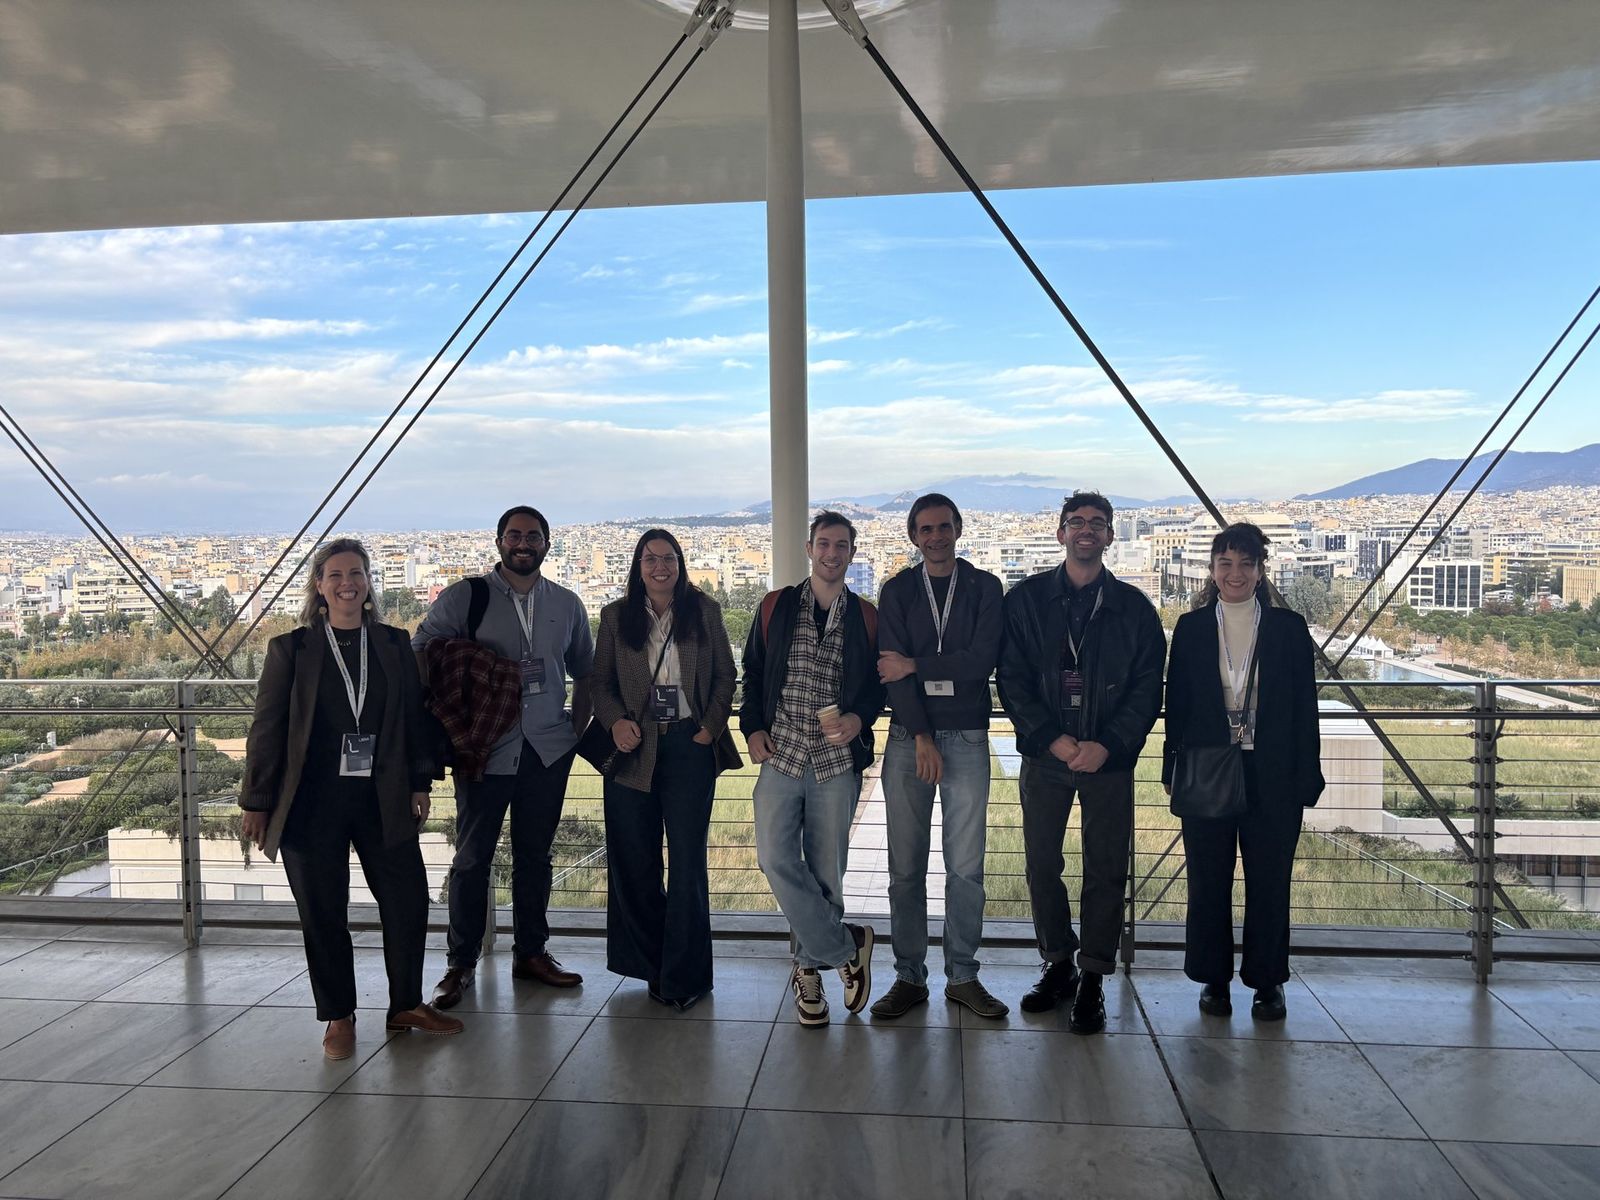
Thank you to the GenAI Summit team for bringing the community together. We were glad to support this year’s summit as a Gold Sponsor and share our work on Agentic RAG.
Find more
Learn more about LIBRA AI's work in Generative and Agentic AI: https://www.libramli.ai/projects/case-studies
View the full presentation here: YannisKopsinis_LIBRAAITechnologies-v1.1.pdf